
Choose models on evidence. Improve what matters.
Benchmark models on your actual tasks, languages and operating constraints. A public leaderboard is a useful signal; it does not replace an evaluation of your application.
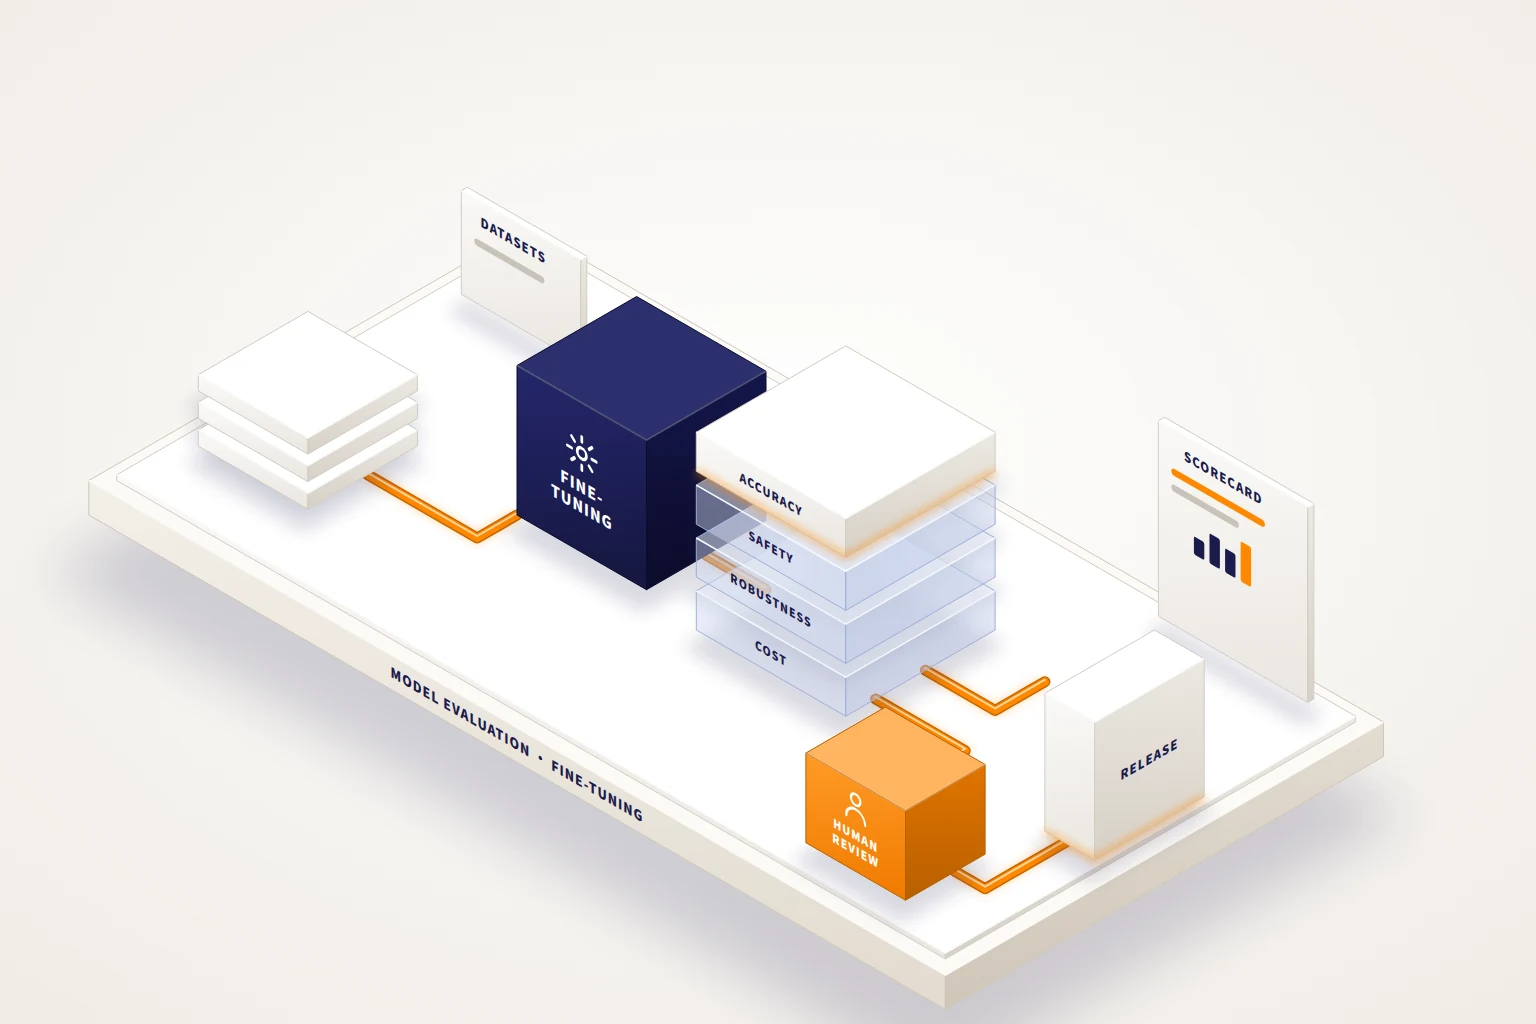
A useful comparison starts with your workload.
Compare Qwen, Mistral and other open-weight or proprietary candidates where they fit the brief. Fix the tasks, evaluation criteria and deployment assumptions before drawing conclusions.
Quality
Does the model succeed on the questions and actions your users actually need?
Economics
What is the end-to-end cost of a successful task at the expected load?
Change
How will you detect regressions before adopting a new version?
Capabilities shaped around your use.

Task-specific benchmarks
Build representative and held-out test sets. Document model version, prompt, configuration, hardware and sampling settings.
Quality, safety & cost
Measure task success, unsupported statements, security behaviour, latency, throughput and total cost on comparable workloads.
Adaptation strategy
Compare a baseline with prompt engineering, retrieval, tools and fine-tuning. Use fine-tuning where the expected gain justifies dataset and lifecycle costs.
Upgrade qualification
Test candidates in isolation, check licences and regressions, then approve a rollout with rollback and production monitoring.
Fine-tuning and retrieval answer different questions.
Fine-tuning changes model weights through training. RAG retrieves information when a request is processed. We evaluate each against a baseline and retain an independent holdout for the final decision. An improvement on development examples is not evidence of general improvement.
Deliverables you can use.
Reproducible protocol
Versioned test data, scoring criteria, configuration and known limitations.
Comparable results
A task-specific comparison of quality, risks, latency and costs under stated conditions.
Adoption decision
A recommendation to adopt, adapt, retain or reject, with a release and monitoring plan.
A clear route from assumptions to evidence.
Define
Specify tasks, success criteria, risk cases and cost assumptions.
Measure
Run candidates with recorded versions and comparable configurations.
Adapt
Test the smallest justified change and examine regressions.
Qualify
Review independent results, licence constraints and release readiness.
Model Evaluation & Fine-tuning, answered
Do you publish a universal model ranking?
No. Model suitability depends on task, data, configuration and deployment. Any published result needs a dated protocol and an identified test set.
What do tokens per second tell us?
They describe part of throughput on a stated setup. We also assess time to first token, end-to-end latency, concurrency and successful task completion.
How do you evaluate security use cases?
We use authorised, bounded test cases with analyst review, measuring detection quality, false positives and remediation usefulness. Coding scores are not treated as evidence of security competence.
When is fine-tuning justified?
When a controlled comparison shows a useful improvement that outweighs data preparation, training, hosting and ongoing requalification costs. It is not the default answer to missing or stale knowledge.
Start with your use case.
Bring the workflow, the constraints and the decision you need to make. Together we can define a useful next step and the evidence it should produce.